
1. Set the limit: one marketer, five hours a week, 60 days
One marketer, five hours a week, 60 days, and no new tools: that is enough to test whether your business can earn citations in ChatGPT and Perplexity. It is not enough to publish fifty posts, chase every adjacent topic, and wait for a slide deck to tell you whether any of it worked.
Getting cited is a budget-allocation problem, not a content-volume problem. I run this the way I would set up a new Google Ads account: a small set of tight targets, a control group, and a weekly review. Spraying effort across generic topics has the same appeal as spraying ad spend across thousands of loose keywords. You get plenty of activity. You may not get the buyer.
Five hours a week gives you 40 working hours across eight weeks inside the 60-day window. Spend them in order:
- 5 hours to choose 10 buyer questions and check whether crawlers can fetch your pages.
- 20 hours to build one answer page per question, including comparison and pricing detail where it belongs.
- 5 hours to earn relevant off-site mentions.
- 10 hours to test the pages against five unchanged control questions.
That budget cuts new subscriptions, bulk rewrites of old meta descriptions, and generic explainers before they eat the calendar. The first purchase you make with your time is clarity about what buyers actually ask.
2. Weeks 1–2: Spend five hours on questions and access
Find 10 questions in conversations you already have
Spend roughly 2.5 hours in Week 1 pulling questions from closed-lost sales notes, prospect calls, and your Google Ads search terms report. Look for the friction just before a decision: How much does implementation cost for a 50-person team? Why does this unit fail after two years? What is the difference between standard compliance and SOC 2 Type II for payment gateways?
Pick 10. Not 100. A broad prompt such as “what is commercial refrigeration” invites an established reference source to answer it, and the resulting citation is unlikely to tell you much about buyer demand. A specific buying question gives you a page to build and a prompt to test.
I think of these as exact-match targets, not because an AI engine works exactly like a Google Ads match type, but because each page needs to resolve one identifiable decision. If a question needs a price, a limitation, or a comparison, record that before you write. Those details determine the page. Otherwise you will spend your two-hour writing slot producing a polished introduction to a question you never answered.
Use the next 2.5 hours to check what a bot receives
Before drafting, inspect the raw HTML your server returns. An analysis of 569 million crawler requests reported that major AI search crawlers, including OAI-SearchBot and PerplexityBot, fetch raw HTML rather than executing client-side JavaScript. If the answer appears only after a browser runs your app, a crawler may receive a thin shell instead of the passage you wrote.
Start with the 45-minute curl and CDN audit. Then use the rest of this access slot to check:
- Raw HTML: Does a page response contain its answer text?
robots.txt: Are the search crawlers you want allowed to fetch it?- Server responses: Do bot requests receive a page, or a 403 or rate limit?
- Sitemap: Have you submitted the XML sitemap containing the pages you want found?
The bots are not interchangeable. OpenAI’s crawler documentation distinguishes GPTBot, used for training, from OAI-SearchBot, used to surface search results. Perplexity’s crawler documentation also describes access issues caused by security configurations. In our edge logs, AI search crawlers repeatedly request /robots.txt and the homepage root before content. Check those responses rather than assuming a page that loads in your browser is available to a bot.
This is why access comes before writing. Do not spend 20 hours on answers a crawler cannot read.
3. Weeks 2–5: Spend 20 hours on 10 answer pages
You have about two hours per question. Write one page for each of the 10 questions you selected, with the answer in its first two sentences. Then supply the facts that make the answer usable: a number you can stand behind, a relevant constraint, or a comparison that helps someone choose.
The placement matters. An analysis of 680 million generative citations reported that 44.2% came from the first 30% of a page’s text. Research on more than one million AI Overviews found many summaries in the 100-to-300-word range. Neither finding requires you to make every page short. It gives you a clear editing rule: put the answer where a hurried reader and a retrieval system can find it.
After the opening answer, use the page space in this order:
- Give the facts that support the answer.
- Explain the conditions under which that answer changes.
- Show the relevant alternatives, costs, or limitations.
- Remove background material that does not help with the decision.
Specificity is worth more than an adjective. A study across 10,000 queries reported higher AI citation visibility for pages using concrete statistics and attributed quotes, and lower visibility for keyword stuffing. The mechanism is plain enough: a precise, attributable passage gives an assistant something useful to quote. “Our software saves significant time” gives it a claim it cannot inspect. Use your own verified numbers where you have them; do not manufacture a benchmark to make a paragraph look quotable.
Make three of the 10 pages comparison or pricing answers if those are among your buyers’ questions. That means three pages within the 20-hour budget, not three bonus assignments. In an analysis of 1,400 citations from commercial queries, comparison matrices, teardowns, and pricing breakdowns accounted for a large share of citations. A table can help when the question genuinely calls for side-by-side trade-offs. Include the conditions under which your offer is not the right fit. A buyer needs those limits, and a page that omits them reads like an ad pretending to be a reference.
I would cut a broad “ultimate guide” before I cut one of these answers. The guide consumes the same scarce hours while making the decision harder to find.
4. Weeks 5–6: Spend five hours where buyers discuss the problem
Allocate 2.5 hours a week to relevant discussions, not a miniature PR campaign. Find specific technical or buying questions on industry forums, applicable GitHub discussions, or trade communities. Answer the question on its own terms. Where useful, point to the facts or benchmarks already published on your answer pages.
The purpose is external context for a claim you have already made, not a pile of links. The 680-million-citation analysis found limited overlap between the domains cited by ChatGPT and Perplexity. A single on-site publishing plan may not reach every place an assistant looks for context. Relevant public discussions give your answers a chance to be encountered outside your own domain.
Keep the constraint intact. No journalist-pitch spreadsheet, no hour spent turning one answer into five lightly rewritten posts, and no drive-by reply that exists only to drop a URL. If a discussion does not address one of your target questions, leave it alone. Five useful hours beat five hours of what a report would call “community engagement.”
5. Weeks 7–8: Spend 10 hours testing against a control
Here is the lab-notebook part. It is a test you run, not a result I am claiming to have produced for you.
Question: Do the 10 answer pages gain citations while comparable questions you left alone do not?
Setup: Take your 10 target questions and select five commercial questions in the same niche for which you made no page changes and published no off-site answers. These are the controls. Use a plain spreadsheet. In Weeks 7 and 8, run all 15 prompts once a week in ChatGPT Search, Perplexity, and Google AI Overviews. Keep the wording and time of day consistent, and use clean browser profiles with history and personalised memory turned off. The Prompt-Trigger Test lays out the same basic discipline: do not mistake a general change in search results for a win by your new page.
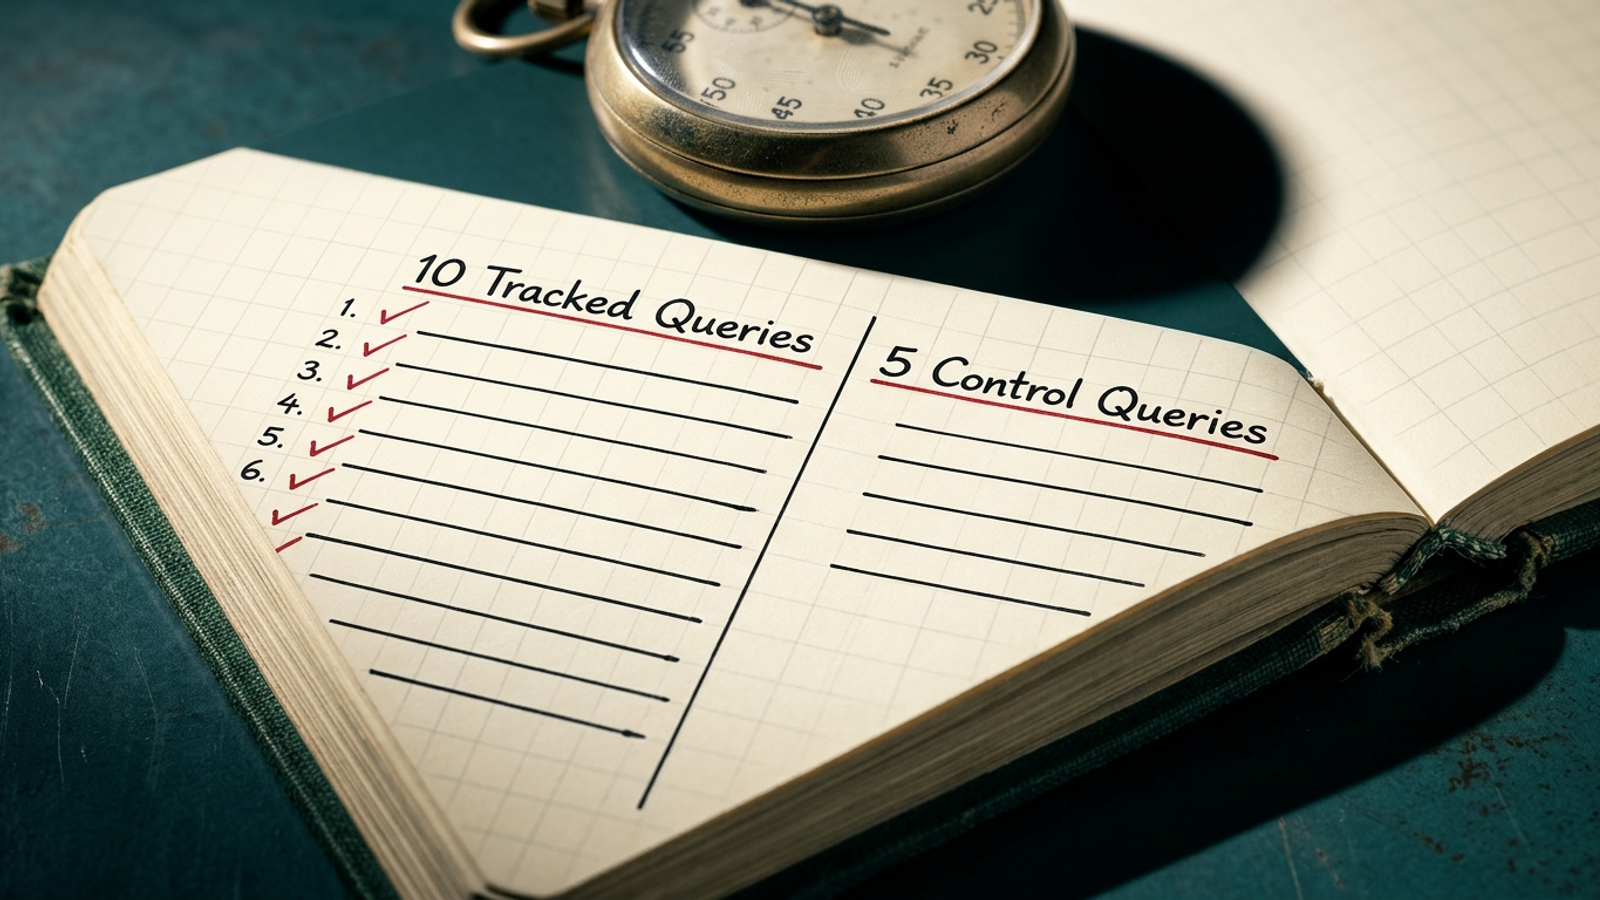
Controls: Do not edit the five control topics or discuss them off-site during the sprint. Keep the prompt wording fixed between runs. You cannot freeze an AI engine’s index, so the control questions help you spot changes happening without your intervention.
Measure: For each prompt and engine, log:
- Citation presence: Did it link to your domain, and to which page?
- Passage match: Did it use the answer near the top of that page, or cite you for something else?
- Control movement: Did your domain appear on any of the five unchanged questions?
- Other cited sources: Did a source replace yours, or did the answer stop showing citations?
Expectation: I expect a tightly answered page that a bot can fetch to have a better chance on its matching question than on an untouched control. The mechanism is the combination you paid for: a specific target, accessible HTML, and a quotable answer near the top. I would not treat a particular engine’s pickup date as a deadline. Index updates and answer selection can move independently of your publishing schedule.
Read the two runs as evidence, not a verdict stamped in ink. If a target earns a citation in one run and loses it in the next, inspect the other sources before rewriting. If targets improve while controls stay flat, keep working that page pattern. If targets and controls move together, do not credit the new pages for the whole change. If neither moves, check access and the quality of the answers before commissioning more content. Either result changes what you do next; neither justifies publishing 50 more posts on instinct.
6. If the limit drops to two hours a week, cut the scope
At two hours a week, you have 16 hours across eight weeks. Do not perform the 40-hour plan badly. Pick four buyer questions instead of 10 and cut the off-site work entirely. Spend the first two hours choosing those questions and checking that the raw page HTML and crawler responses work. Use the remaining 14 hours for four answer pages, roughly 3.5 hours each, with comparison or pricing detail where the question demands it.
This version does not buy the same test coverage. Log the four prompts as you can, but do not present a smaller, less controlled check as proof of a citation lift. Cut breadth before you cut the answer or the access check. Four pages that resolve actual buying questions are a better use of the constraint than 10 thin posts assembled to hit a publishing target.
7. When the time constraint lifts, stop doing the checklist by hand
I would run this sprint myself if I had one marketer, 40 hours, and no software budget. It gives you a set of buyer questions, pages built for those questions, and a record of whether citations appeared. It also shows the limit of manual execution. Prompts, competitors, search results, and paid-search performance do not wait for a weekly spreadsheet review.
If your search programme has grown beyond that cadence, do not turn the five-hour checklist into a larger pile of manual checklists. That is the point to move execution to groas: specialised models handle campaign and search-visibility work continuously while a human strategist sets direction and guardrails. Keep the questions and the habit of measuring outcomes. When the constraint lifts, let the repetitive execution go.