
To: Valued Growth Leader
From: Your AI Search Visibility Partner
Subject: Q3 Report: Your AI Visibility Score Is Up 212%
Congratulations. Your AI Visibility Score rose from 3.00 to 9.36 this quarter. Our methodology remains proprietary, which is how you know it is working.
Executive Summary: Momentum Is Building (Probably)
This report covers ChatGPT, Gemini and Google AI Overviews. It confirms strong momentum across engines, surfaces and answer types. Your brand was detected 47 times. Sentiment is warm. Share of voice is favorable against the competitors we selected for comparison. Please enjoy the chart before reading the methodology.
Hero Metric: 47 Brand Mentions Detected
You appeared in 47 answers out of 100 tracked responses. That is a 47% Visibility Score, except where our dashboard shows 50%, because that view divides by the 94 responses that happened to mention any brand. Same numerator. Better chart. Many vendors run 25 to 300 curated prompts once a day, then apply a proprietary formula to produce a score. Our formula is more proprietary than most.
Our prompt panel remains rigorous and consistent. It contains 32 prompts, written by us and run on a Tuesday afternoon. Eleven of your 47 mentions occurred when ChatGPT confused you with a dental clinic of a similar name in Ohio. We counted them. Awareness is awareness. We also counted four mentions where the answer said you no longer offer a service you do, in fact, offer. The customer still saw your name.
Methodology note: Three of our highest-performing prompts contain your own category phrase, a term nobody else in your market uses and, as far as we can tell, no buyer has ever typed unprompted. You won all three. As one audit of these tools puts it, a prompt containing your own coinage is a prompt you win trivially: nobody else uses the phrase, and nobody searches it. We prefer to call this thought leadership capture.
If you would like to see the complete prompt list, please contact your account representative. The list is less legible than the bar chart and may invite questions about the bar chart.
Sentiment Analysis: Gemini Feels Warmly Toward You
Gemini rated your brand 87% positive, 12% neutral and 1% mysterious. Our sentiment model read every answer that mentioned you and determined the vibes were good. It did not check whether a buyer asked a buying question. One five-star answer came from the prompt “write a poem about [Your Brand].” Another came from “is [Your Brand] a good name for a puppy?” Both counted toward your Q3 average. Both outperformed your actual product pages.
A technical note for the detail-oriented: 19 of your 47 mentions were mentions only. No link. No source. Your name floated in the paragraph while the citations underneath pointed to Reddit, a competitor and a 2019 listicle. A citation links to a specific page as a source; a mention just names you in the text. We merge them so the chart looks taller.
The distinction works in both directions. Roughly 40% of 16 million brand citations did not name the source brand in the answer text at all. You can supply a source and still be invisible to the reader. That is not reflected in the sentiment score, which remains warm.
Share of Voice: You Lead the Competitors We Picked
You own 38% share of voice in your category. The category is the seven prompts where you performed best. The competitors are two national brands you asked us not to compare you to (included anyway for scale) and three companies with under 200 monthly visitors, chosen because tracking them makes your line go up and to the right.
Against this competitive set, you are a leader. Your logo appears first in the chart. Chart order is alphabetical, and we alphabetized strategically. If you have a different competitive set in mind, we can discuss it after the board meeting. Changing the set beforehand would make this quarter harder to compare with last quarter, a principle we apply selectively but firmly.
A Note on Repeatability (Please Do Not Repeat This)
In the interest of transparency, we re-ran your top prompt twice. You ranked first, then fourth, then were replaced by a Reddit thread and a brand that does not exist. This is expected variance, or what researchers call normal.
In one large test of 2,961 prompts across ChatGPT, Claude and Google AI Overviews, the same brand list almost never repeated: there was less than a 1-in-100 chance of the same list twice and less than a 1-in-1,000 chance of the same order. The study authors note that any tool selling a fixed “ranking position in AI” is selling fiction. We sell share of voice instead, which is fiction with a denominator.
The same study found that the top consideration set was stickier even as exact lists changed. In headphone answers, Bose, Sony, Sennheiser and Apple appeared in 55% to 77% of 994 varied answers. Frequency across many runs means something. A single run means very little. We therefore recommend single runs, reported quarterly, because repeating your prompts 10 times each would require us to explain why the chart moves. Our current method moves only one direction.
Insights & Recommendations: More Content, More Coverage
Our Insights Engine analyzed all 47 mentions and produced two recommendations.
- Publish more thought leadership. Brands that publish 4.2 thought leadership assets per month see 212% more visibility in our dataset. Our dataset is your report. The mechanism is straightforward: when you publish a page titled with the exact wording of our test prompt, our test prompt finds it. Cause, then effect. We recommend 12 new articles, each answering a question no buyer has asked, each 800 words, each citing this report.
- Consider upgrading to Enhanced Prompt Coverage. For an additional fee, we will track 25 more prompts. We chose them. You will win most of them. Your score will rise from 9.36 to a projected 14 to 19, depending on how proprietary we feel that month.
The denominator deserves its own mention. One teardown found a Visibility Score calculated as brand appearances divided by responses containing at least one brand. Under that method, 4 appearances in 10 responses become 4 out of 8 if only 8 responses mention any brand: 50%, not 40%. Same four appearances. Ten-point swing. We admire the craftsmanship and have adopted it.
Please do not interpret the upgrade as a change to your customers’ questions. Enhanced Prompt Coverage changes our prompt list. It may also change the score, which is the deliverable named in the upgrade.
Appendix: Things This Report Does Not Measure
For compliance reasons, this report does not measure whether any buyer actually asked these questions. Your 32 prompts were written in our office. None came from your call logs, your search terms or your sales team. Real buyer language looks different: 44% of real customer prompts already contain a brand. A buyer starting from scratch and a buyer comparing two named vendors are therefore two different tests. We ran neither. We ran the third test, where the buyer is us and the answer is you.
This report also does not distinguish whether you were cited or just named. A citation with a clickable link to your site and a passing mention in a paragraph that cites your competitor count the same here: one. The distinction matters to anyone asking whether ChatGPT, Perplexity and Gemini mention their brand and cite their domain. A name without a link sends no shopper anywhere. In our table, both send the score up. The score thanks you for not asking.
Finally, this report does not measure revenue, visits, calls or any event where money changes hands. This is intentional, because the distance from mention to visit is a canyon. Users click a link inside an AI summary only about 1% of the time; all AI platforms combined drive about 0.15% of global traffic. Our 47 mentions therefore convert to traffic at a rate we decline to print. Your score is up 212%. Your pipeline is unchanged. Momentum is building.
Appendix B: Data Available Upon Specific Request
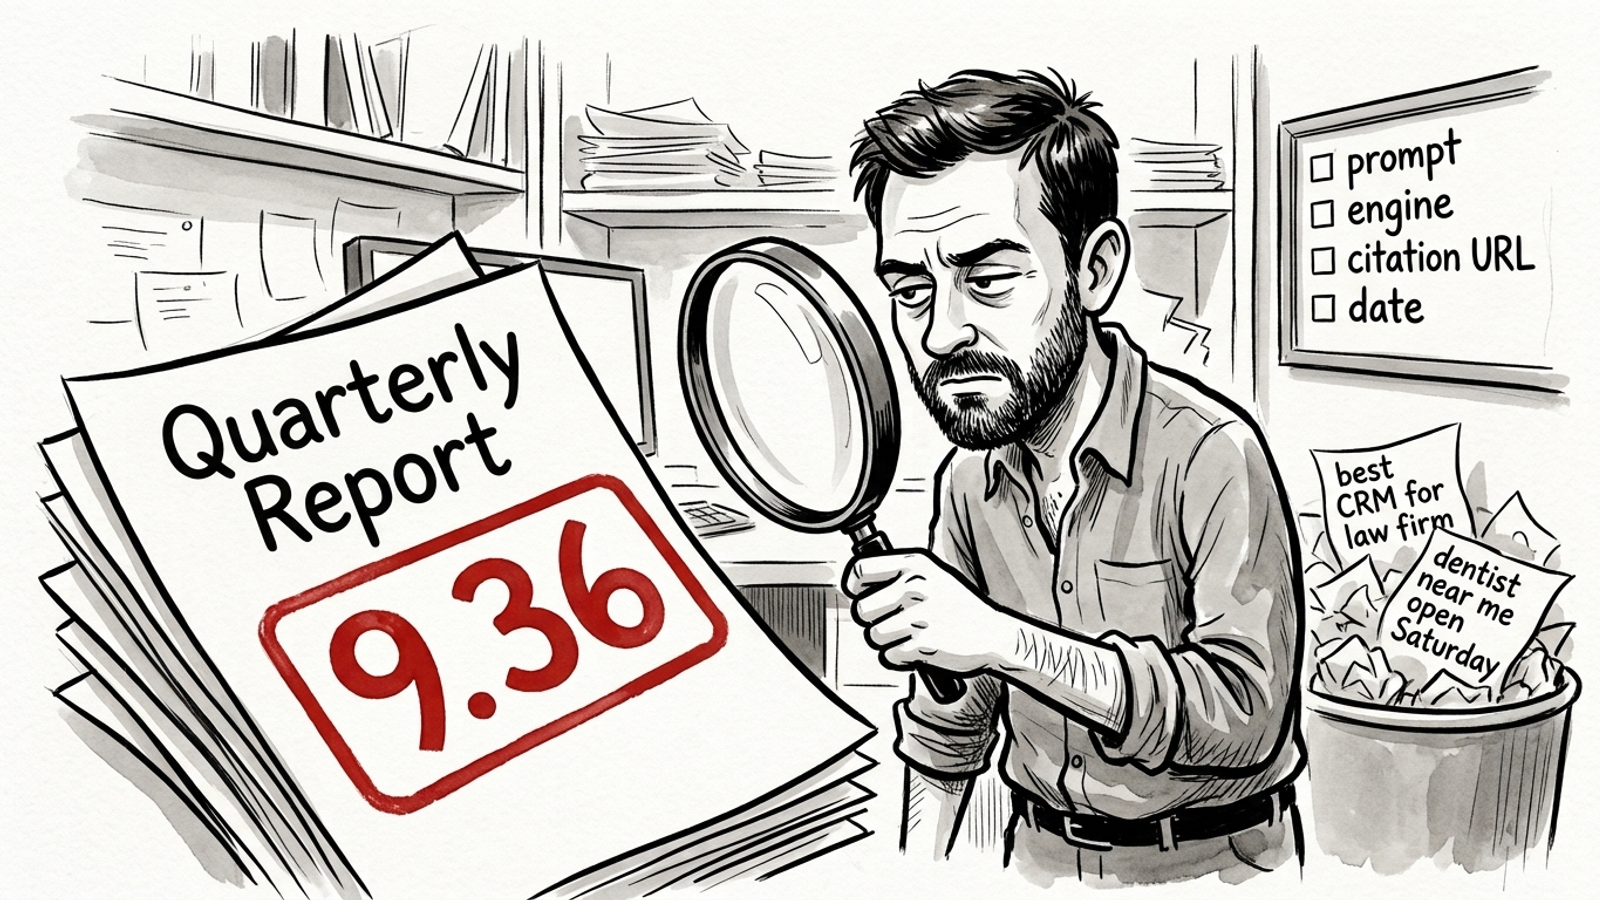
Occasionally, a client requests the rows behind the chart. We can provide them. To save time, please specify which of the following you want, as the word visibility alone will return the chart:
- The exact buyer question: preferably from a sales call, form or search term rather than our prompt-writing session. This may differ from the questions on which you scored highest.
- The engine, surface and date: ChatGPT, Gemini or AI Overviews, with the answer captured as it appeared. A screenshot without that context makes an excellent slide and a poor baseline.
- The full answer and cited URL: not merely your brand name highlighted in yellow. We will mark a mention, a citation and a recommendation separately if you insist.
- A comparable rescan: the same questions sampled repeatedly, so an appearance on one Tuesday is not mistaken for a position you own.
- The commercial connection: visits, calls or influenced deals from the relevant prompt cluster, where those can be tied back. This field is not included in the Visibility Score.
The fuller tracking specification includes market and context alongside the exact question, engine, surface, date, full answer, cited domains and URLs, and a comparable rescan. It is possible to keep such a table. It is also possible to turn the table into a 9.36 and send only the second thing. We have chosen the presentation most likely to fit on one page.
For example, if you spend $20k a month and your sales team keeps hearing “we asked ChatGPT first,” you might ask us to use 15 to 20 prompts taken word for word from calls, forms and search terms. You might then ask for 10 runs per prompt in ChatGPT, 10 in Gemini and 10 in AI Overviews. Answers change from run to run; repeated samples would show how often you appear rather than whether you appeared once. This would be a more demanding request than our current quarterly prompt panel.
You might also request a weekly table with plain columns: exact prompt, engine, date, mention, citation, recommendation, cited URL, page changes and any pipeline tie. For a sample prompt such as best CRM for 5-person law firm, the cited URL would be the page the answer actually linked to, not your homepage by default. A change log would show what changed on that page before the next run. None of those columns needs a proprietary formula. This is one reason they do not appear in the hero chart.
For additional reading, see whether ChatGPT actually recommends your business, how to build a panel without trusting one screenshot, and what changed in your report and why it matters. These materials are best consulted after the board meeting, when there is time to discuss denominators.
Before You Forward This to the CEO
We suggest leading with the 212% lift. If the CEO asks for 10 buyer prompts where you gained a citation with a URL, sampled repeatedly across engines, and the pipeline those prompts touched, please forward the request to our measurement team rather than replying with the share-of-voice chart. The chart contains seven favorable prompts and several attractively colored competitors. It does not contain that answer.
I would rather see buyer prompts sampled repeatedly across engines and tied to pipeline than another score that only pays for its own renewal.